Commentary: A Creation Must Have a Creator: Who Owns an AI-Designed AMVCA Look?
A creation must have a creator. For centuries, our understanding of who can be a creator has been relatively straightforward: a person (or group of people). A person conceives an idea, exercises judgment, makes creative choices, and transforms those ideas into original work. In copyright law, this thinking creator of an original work is referred to as an author in whom copyright is automatically vested[1]. However, artificial intelligence (AI) has walked into the room and brought along with it – complication around this once settled understanding.
Generative AI (GenAI) systems can now produce text, images, music, videos, and designs within seconds of receiving a prompt. As these technologies become increasingly integrated into creative industries, they raise fundamental questions for copyright law. Can an AI system be regarded as an author? Can AI-generated works attract copyright protection? If so, who owns that copyright? And what happens where an AI-generated output resembles a pre-existing work?
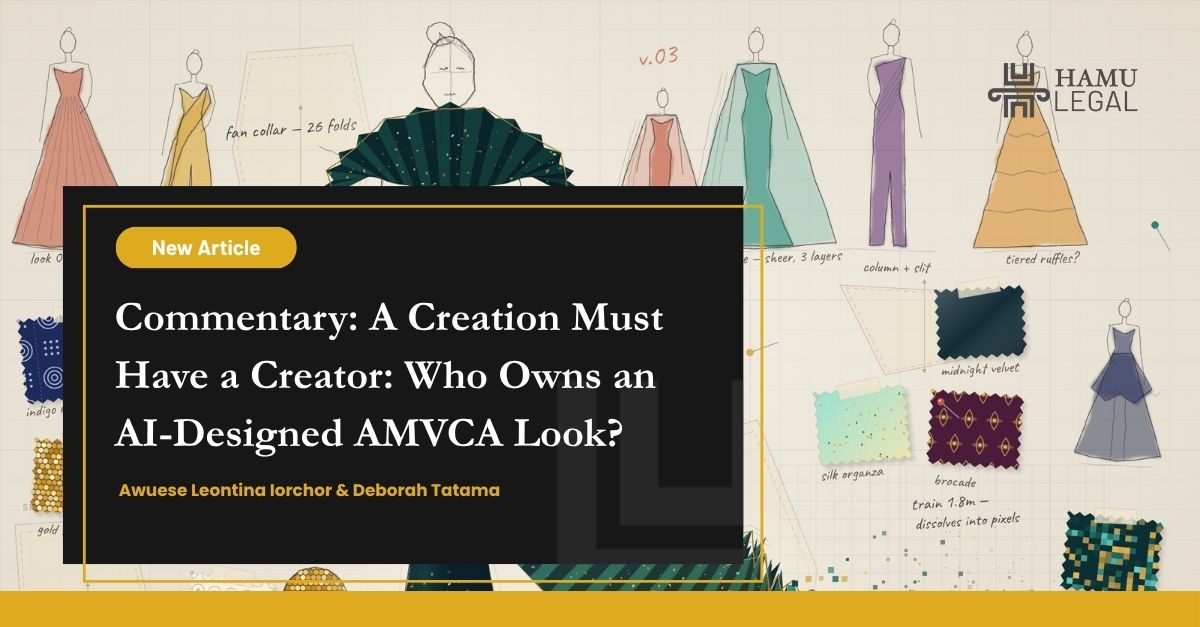
These questions gained renewed relevance following discussions surrounding fashion creations showcased at the 2026 Africa Magic Viewers’ Choice Awards (AMVCA). The event, celebrated as much for its fashion as for its entertainment awards, featured a number of striking and innovative red-carpet looks that generated significant public attention. Alongside the admiration, however, came conversations about the role of AI in fashion design and the extent to which AI-assisted creative processes may intersect with copyright law.
Many creators increasingly rely on GenAI systems during the conceptualization stage of fashion design. This trend raises legitimate questions about authorship, originality, attribution, and the possibility of inadvertent reproduction of existing works.
Who can be an author under Nigerian copyright law?
Under the Nigerian Copyright Act, 2022, copyright is initially ascribed to the author of the work, except agreed otherwise by agreement[2] . To understand who the author of a work is in any creative scenario whether musically, in literary works, artistic works, etc., the Act refers to an author in each case to the “person” who creates. In the current Nigerian regulatory reality, a GenAI software cannot be an author and consequently, cannot own copyright. In this context, “person” may encompass a natural person or a juristic person where the law recognises the latter as capable of holding rights. However, a GenAI system is not presently recognised under Nigerian law as a juristic person or other legal person capable of being an author in its own right
Copyright law has traditionally linked authorship to human intellectual effort and the very concept of a moral right means that it can only be ascribed to an entity with agency, awareness, original choices, and original preferences – all attributes an AI is incapable of; as we would argue that current AI systems do not possess consciousness, intention, preferences, or independent decision-making abilities.
Can AI-Assisted Works Attract Copyright Protection?
A more important consideration is in the more intrinsic aspects of copyright and creativity. A copyright comprises both an economic and moral right. While an economic right can be transferred, a moral which refers to the integrity and authenticity of the work; the expectation that at all times, any exploitation of a work must reflect the integrity, authenticity, values, and soul of the original work; cannot be transferred. It is a constant that always remains with the author which allows such a person to[3]:
- Claim authorship of their work, in particular that their authorship be indicated in connection with any exploitation of the work[4]; and
- Object and to seek relief in connection with any distortion, mutilation or other modification of, and any other derogatory action in relation to the work, where such action would be or is prejudicial to their honour or reputation.
Copyright law has traditionally linked authorship to human intellectual effort and the very concept of a moral right means that it can only be ascribed to an entity with agency, awareness, original choices, and original preferences – all attributes an AI is incapable of; as we would argue that current AI systems do not possess consciousness, intention, preferences, or independent decision-making abilities.
GenAI is a type of artificial intelligence that can create content, such as text, images, music, and even video, by learning patterns from existing data.[5] Large language model software like OpenAI’s ChatGPT, Microsoft’s Copilot, and Google’s Gemini, all use GenAI. However, GenAI does not create from a vacuum, nor does it create from its “mind”. As mentioned, it relies on preexisting data. How does this work? GenAI is trained on documents and other data that already exist, and it “learns” from these datasets so it can predict outcomes in the same ways humans might create on their own[6]. In essence, while the output may appear original, the process by which they are generated differs fundamentally from human creativity as traditionally understood by copyright law.
Who Owns the Copyright in an AI-Assisted Creation?
This is how a person is able to prompt a GenAI tool to draft an agreement with nuances like “make it sound professional” or “use legalese”. It is how a blogger may prompt it to draft an article based on the style of a particular author. It is how AI can create covers of an existing song using an artiste’s style and voice – The FAVE “Intentions” saga
An understanding of how GenAI works supports the fact that a GenAI does not think or create in itself. This understanding should reduce the comfort of the prompter/user who completely delegates creative thinking or the creation of artistic, musical, or literary works to their AI system. Caution should not be thrown into the wind due to the fact that GenAI only creates based on the data it has been trained with. It sits on and is learning from a deluge of original work from which it further creates and it would not be prudent to completely rely on the originality of its output.
What Happens Where an AI Output Resembles an Existing Work?
The case of The New York Times vs. Open AI, where the New York Times sued OpenAI and Microsoft for the unpermitted use of Times articles to train GPT large language models – paints a perfect picture. The facts centre around the use of copyrighted works in the development of generative AI tools, namely OpenAI’s ChatGPT and Microsoft’s Bing Chat or Copilot, both of which are built on top of OpenAI’s GPT Model. These two large language models (LLMs), are built by “training” on massive corpora of text and they incorporate information from these datasets and “learn” the patterns of words within a given context. Then, when provided with a prompt, the LLM can generate a natural-language response to the user’s prompt. In the Harvard Law review of this case, it was stated that the latest models of GPT are trained on trillions of words[8] – a dataset argued to be so large it could be “the equivalent of a Microsoft Word document that is over 3.7 billion pages long.” The pillar of Times’s claim is that this dataset contains a “mass of Times copyrighted content.”[9]
Time’s argument was that this results in the infringement of copyright(s) through the unlicensed and unauthorized use and reproduction of Times works during the training of its models. However, one of the key issues noted during its argument was that LLMs sometimes “memorize” parts of the works included in training data such that, the models can occasionally generate “near-verbatim” reproductions of the works.
Bringing this back to the case of artistic works – fashion sketches, while a GenAI may not directly lift an existing design, it may from its training or memory, produce something so similar or close to an existing design that should at the very least require a credit/reference to the original designer.
What Does This Mean for Fashion Creatives?
The question is not whether AI should be used in creative industries. It already is. The more pressing question is how creators, technology companies, and regulators can ensure that innovation does not come at the expense of the fundamental principles that copyright law seeks to protect.
Copyright law was never intended to stifle creativity, but rather, to protect the rights of authors and to ensure just rewards and recognition for their intellectual efforts[10]. As GenAI assisted creation becomes increasingly a norm, these objectives remain just as important.
For users of generative AI, the lesson is not to abandon these tools but to engage with them responsibly. Before proceeding to translate a sketch to a physical design, consider a few things. AI should be treated as an assistant, not a substitute for human creativity. Meaningful human contribution, critical evaluation of outputs, and appropriate attribution where necessary remain essential.
For AI developers, greater transparency regarding training data, influences, and potential source material would help users make informed decisions and reduce infringement risks.
In conclusion, while AI may assist the creative process, copyright law continues to recognise a fundamentally human concept at its core. Until the law evolves otherwise, originality remains inseparable from human creative effort.[11]
Authors
Awuese Leontina Iorchor & Deborah Tatama
References
- Nigerian Copyright Act 2022
- SAP, “What is Generative AI?”. https://www.sap.com/resources/what-is-generative-ai.October 6, 2026
- Coursera, “What is Generative AI?” . https://www.coursera.org/articles/what-is-generative-ai. October 6, 2026.
- Olawumi Odunayo Faidat. How Fave Transformed an AI Remix into Art. https://www.deedsmag.com/stories/how-fave-transformed-an-ai-remix-into-art. Assessed October 6, 2026
- Harvard Law Review, “The Times’s About-Face: How the New York Times’s Lawsuit Against OpenAI Could Reshape AI” (2024) . https://harvardlawreview.org/blog/2024/04/nyt-v-openai-the-timess-about-face/ . Assessed October 6, 2026
- The New York Times Company, Complaint (December 2023). https://nytco-assets.nytimes.com/2023/12/NYT_Complaint_Dec2023.pdf. Assessed October 6, 2026
[1] Section 28(1) Copyright Act 2022
[2] Section 28(1) Copyright Act 2022
[3] Section 14(1) Copyright Act 2022
[4] Section 10(1) Copyright Act 2022
[5] https://www.sap.com/resources/what-is-generative-ai
[6] https://www.coursera.org/articles/what-is-generative-ai
[7] Olawumi Odunayo Faidat. How Fave Transformed an AI Remix into Art. https://www.deedsmag.com/stories/how-fave-transformed-an-ai-remix-into-art. Assessed October 6, 2026
[8] https://nytco-assets.nytimes.com/2023/12/NYT_Complaint_Dec2023.pdf
[9] https://harvardlawreview.org/blog/2024/04/nyt-v-openai-the-timess-about-face/
[10] Section 1, Copyright Act 2022
[11] Section 2(2) Copyright Act